Base camp · POC
Camp I · Diagnose
Camp II · Build pipelines
Camp III · AutoDQ
Summit · Production
Proudly Canadian · Toronto & Montréal
Databricks production acceleration partner

Databricks is deployed.
Now take it to the summit.

You've chosen Databricks. Now let's get your investment to work: pipelines live, data ready, and your first workload in production within 90 days.

NewClaude implementation as a registered Claude partner · Informatica CDGC & CDQ
Scroll to climb
Base camp · Where programs stall

Most teams get
stuck in POCs.

Use cases in production bring the real value. We take one real use case all the way up, with reliable pipelines and data quality embedded from the start.

Camp I · Diagnose & select · Weeks 1–2

Choose the right
route first.

We assess your environment, prioritize use cases, scope the data tightly and select one realistic, high-impact use case. Output: a clear execution plan with controlled scope.

Camp II · Build & stabilize · Weeks 3–8

Bronze, silver,
gold.

Pipelines built through the medallion layers, reliability issues fixed at the source and performance optimized. Output: working, validated pipelines.

Camp III · Data quality with AutoDQ

Trust the data
on the way up.

AutoDQ is included in the engagement, free. It runs natively on Databricks with Unity Catalog, generates and enforces rules automatically, and catches issues before downstream impact.

Summit · Weeks 9–12

Live in production.
Then the next peak.

1use case live in production
2–4more use cases scoped
90days, fixed scope

Validated with business users, with a clear path to scaling usage. Not a POC. A live workload.

Registered Claude partner

Claude, implemented for the enterprise.

KData is a registered Claude partner. We help enterprise teams put Claude to work: choosing the right use cases, connecting Claude securely to their data and tools, and rolling it out with governance and adoption built in.

ClaudeRegistered partner
  1. 01Use-case selection

    Find where Claude creates measurable value, from document-heavy work to analysis and engineering.

  2. 02Secure integration

    Connect Claude to your data and tools with the right access controls in place.

  3. 03Governance

    Usage policies, data handling and human review designed in from the start.

  4. 04Adoption

    Enablement and rollout so teams keep using Claude well, beyond the pilot.

Already on Databricks? We implement Claude alongside your governed lakehouse, so AI works with the same trusted data, definitions and access controls as the rest of your platform.

Plan a Claude pilot
About KData

A Databricks partner that gets you to production.

databricksPartner
CanadianToronto · Montréal

KData is a Canadian, Databricks-focused consulting partner, based in Toronto and Montréal, that helps enterprises move from pilots to production. We build reliable pipelines, governed lakehouse architectures and production-ready use cases directly in our clients' environments, delivering real outcomes, not just prototypes.

50+team members
EN / FRdelivery across Canada
2–5senior experts per engagement
Clauderegistered partner
Why we exist

Where Databricks programs stall

The patterns are consistent. We clear these first.

Pattern 01

Unreliable pipelines

Not production-grade. Constant rework.

Pattern 02

Weak gold layer

Poor modeling limits consumption.

Pattern 03

Manual validation

Data is trusted too late.

Pattern 04

Late governance

Introduced after scale, slows everything down.

Canadian enterprise focus

Local guides. Deep roots in Québec.

Fully comfortable operating in English and French environments.

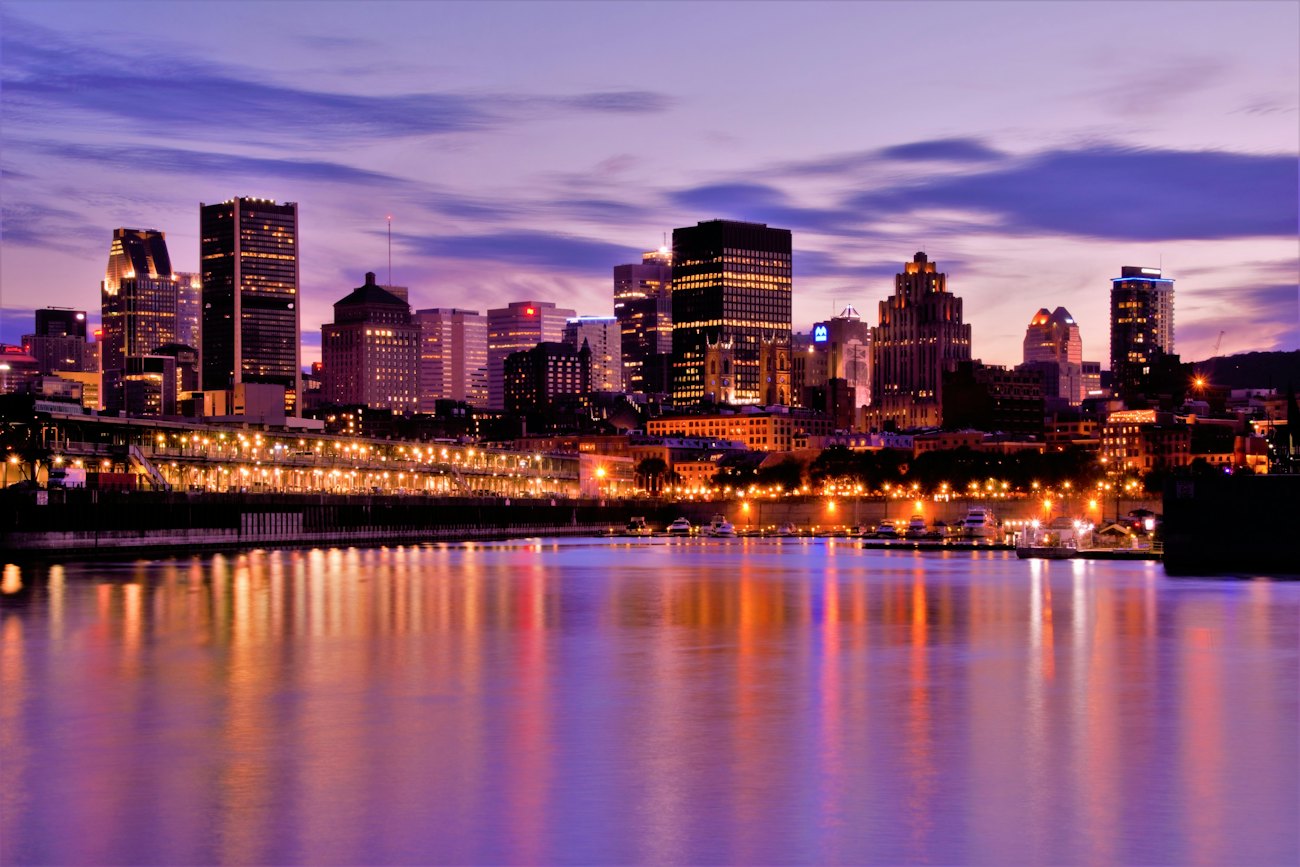
Montréal skyline at dusk across the water

Montréal

Québec · FR / EN
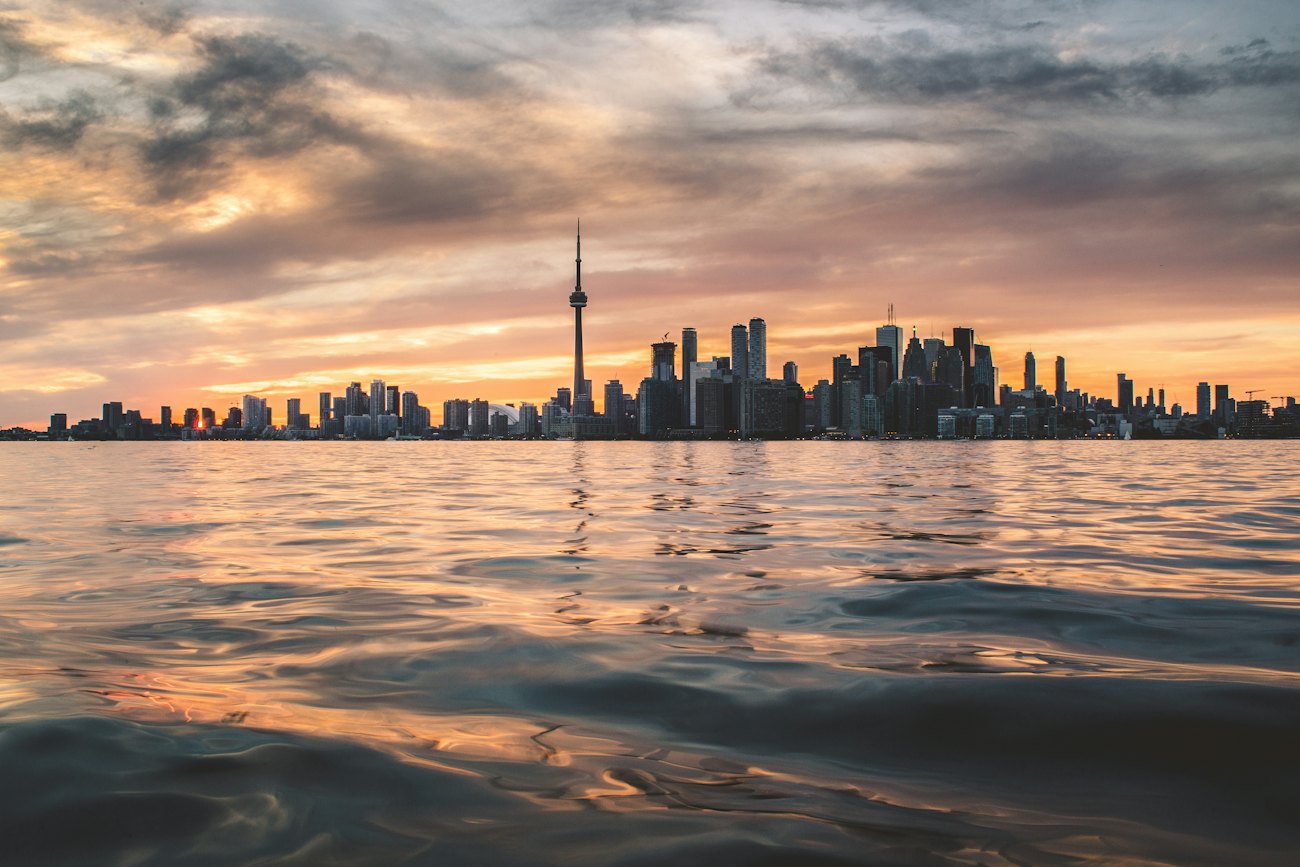
Toronto skyline with the CN Tower at golden hour

Toronto

Exchange Tower · King St W
Services

Enterprise Databricks execution.

We stabilize pipelines, improve data reliability and move real workloads into production. A consulting partner embedded with your team, focused on execution, not theory.

Implementation & Migration

Legacy SQL, ETL and warehouse logic translated, validated and optimized for Databricks.

Optimization & Performance

Pipelines tuned for cost and reliability, with stronger orchestration, testing and operational discipline.

Advisory & Strategy

Platform structure and governance introduced without slowing delivery, tied to real platform ROI.

Generative & Agentic AI

Private LLMs, RAG and governed AI agents on Databricks, from strategy to production.

Staffing & Talent Delivery

Databricks-certified engineers who join your team and work hands-on, not advisory-only.

Migration routes

Every legacy platform has its own route.

Plus Snowflake, Redshift, Hadoop, Oracle and 15+ more with AI-powered migration tooling.

Most travelled01

Netezza → Databricks

Every SQL workload and ETL dependency inventoried before scoping. Pipelines sequenced by lineage, not convenience.

8000+ entities · 4000+ pipelines · 5 PB+
Platform redesign02

Teradata → Databricks

BTEQ scripts, stored procedures and macros converted and refactored, so Teradata-specific patterns stay behind.

BTEQ · FastLoad · MultiLoad
Platform redesign03

IBM DB2 → Databricks

Schema, SQL, stored logic and ETL reassessed, so obsolete, low-value workloads don't make the trip.

Schema · SQL · stored logic
Enterprise data warehouse04

SQL Server → Databricks

T-SQL, stored procedures, SSIS packages and SQL Agent jobs refactored, including identity columns and dynamic SQL.

T-SQL · SSIS · SQL Agent
Analytics workloads05

SAS → Databricks

Macros and DATA steps refactored for distributed execution, with decimal precision and compliance mapping checked.

Macros · DATA steps · stored processes
Implementation06

Databricks on GCP

Architecture before deployment: operating model, service accounts and Unity Catalog governance designed first.

IAM · networking · Unity Catalog
AI on Databricks

From production data to governed AI.

Once data is reliable in production, it can power AI.

Generative AI

Private LLMs on your own data

Build, tune and serve private LLMs with Mosaic AI, Unity Catalog, Delta Live Tables and Databricks Workflows, with MLOps and AutoDQ for responsible delivery.

  • Assess & prepare
  • Build & integrate
  • Operationalize & monitor
  • Adopt & scale
Agentic AI

Agents grounded in governed data

Agent Bricks and Vector Search reasoning over your Delta data, with AI Gateway, lineage, access controls and evaluation pipelines implemented end to end.

  • Customer support
  • Document intelligence
  • Operations
  • Compliance
Offerings

Packaged to ship.

A fixed-scope program and free accelerators, built from real enterprise delivery experience.

Go-Live in 90 Days

A fixed-scope expedition.

For organizations that have already chosen Databricks and are ready to go live. One use case, end to end, delivered by a team of 2–5 senior experts.

WEEK 0WEEK 2WEEK 8WEEK 12 · LIVE
Phase 1 · Weeks 1–2

Diagnose & select

Assess the environment, prioritize use cases, scope data tightly and pick one realistic, high-impact use case.

Output: clear execution plan
Phase 2 · Weeks 3–8

Build & stabilize

Bronze → silver → gold pipelines, reliability fixes, AutoDQ embedded and performance optimized.

Output: working, validated pipelines
Phase 3 · Weeks 9–12

Production & scale

Deploy to production, validate with business users and define the next use cases.

Output: live workload and roadmap
Who it's for
  • Organizations that have already chosen Databricks
  • Teams with at least one defined use case
  • Data initiatives under delivery pressure
  • Environments limited by reliability issues
Who it's not for
  • Teams still exploring Databricks
  • No defined use case
  • No access to data
  • No stakeholder availability
Engagement$34,495

Fixed scope, 90 days. Aligns with Databricks' Pilot to Production initiative, with co-selling and co-funding options available.

See if you qualify
Engineers mapping a data architecture on a whiteboard
Pre-built rules200+
With Go-Live in 90Free
Accelerator · AutoDQ

AI-powered data quality, native to Databricks.

AutoDQ automatically generates data quality rules, monitors your pipelines in real time and explains issues in plain language. Teams validate data in hours, not weeks.

  • ✓
    Real-time monitoring

    Continuous anomaly detection and alerting across your critical pipelines.

  • ✓
    Automated validation

    Schema, format, business-rule and cross-table referential checks.

  • ✓
    Smart remediation

    GenAI explains issues and suggests fixes, with approval workflows and full audit logs.

  • ✓
    Runs natively in Databricks

    No new software to install. Scales with your lakehouse and Unity Catalog.

Also from KData · i-QA

Upload a business requirements document and get a complete, production-ready test suite for UI, APIs, databases and business logic. It runs entirely on your own infrastructure: no cloud, no external APIs.

Case studies

Built for how teams actually work.

Recent KData work in finance automation, fleet analytics, platform migration and data quality, plus an i-QA product story. Client names are withheld unless the client shares a named success story.

Finance automationConnected workflows
Case study 01

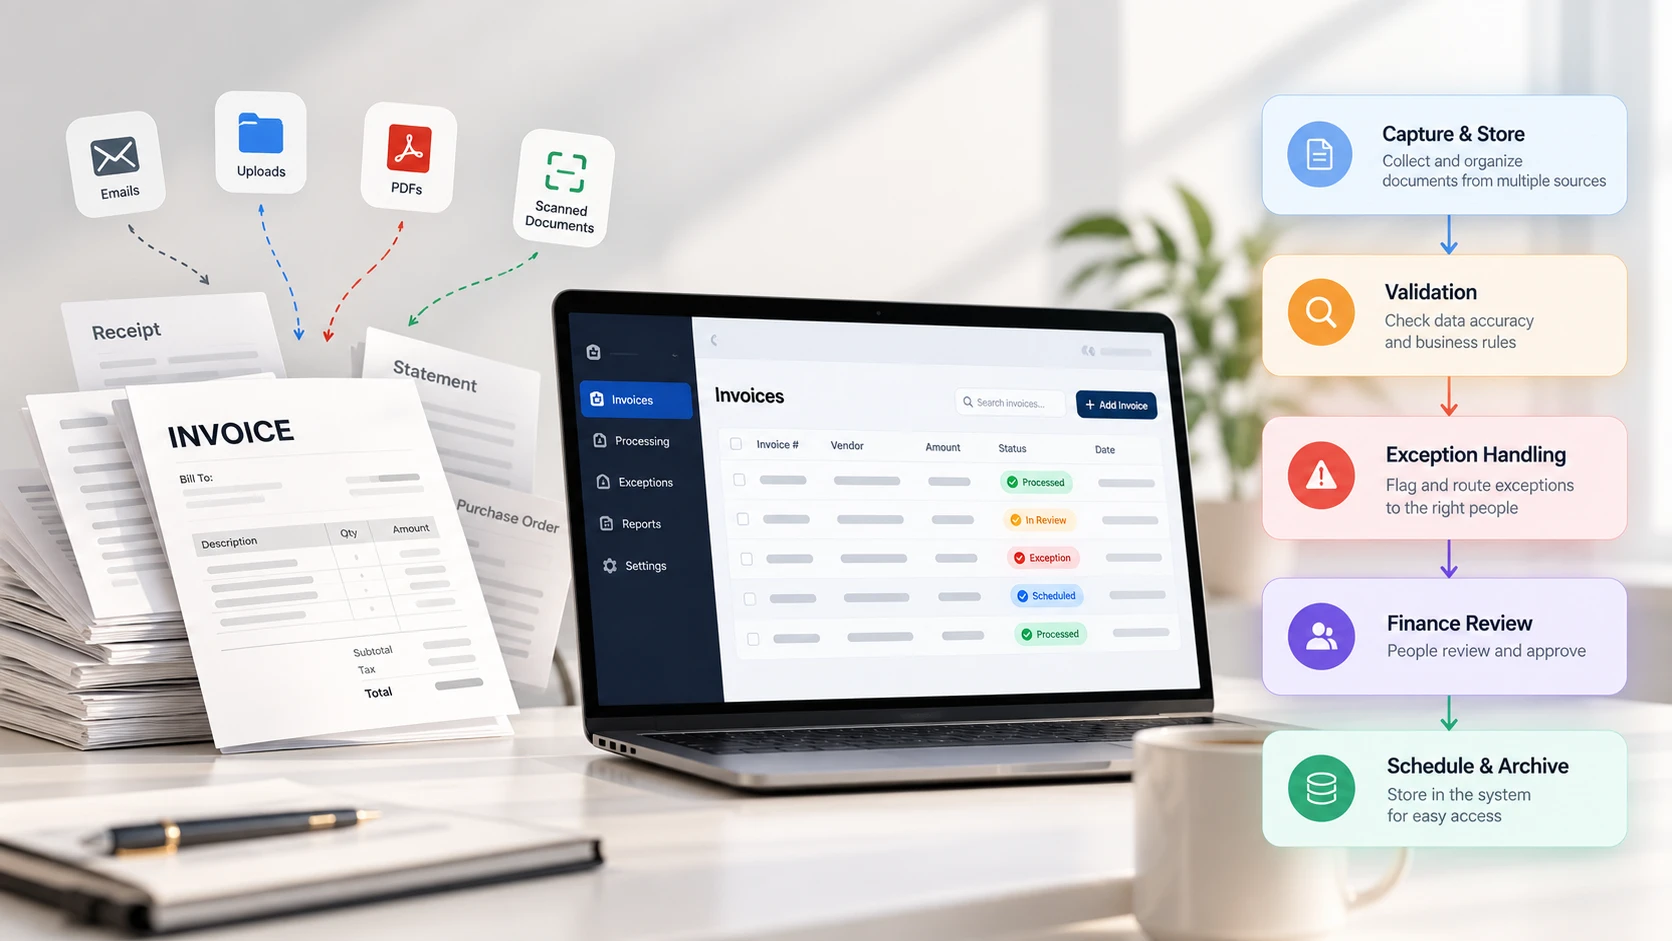
Automated invoice processing, built for everyday operations

Keep invoice processing moving without relying on manual handoffs or an employee's laptop. KData helps organizations connect invoice intake, document handling and processing workflows through a centrally hosted solution.

Talk to us about finance automation
Success storySee the named version: Endurance Environmental with Claude AI →
Invoice automation overview: emails, uploads, PDFs and scanned documents flow into one invoice queue with processed, in review, exception and scheduled statuses, through five stages: capture and store, validation, exception handling, finance review, and schedule and archive
Solution overview · click to enlarge
The business challenge

Invoices often arrive through disconnected channels, leaving finance teams to collect attachments, organize documents and move information between systems. Desktop-dependent automation adds another limit: processing stops when the application closes or the device goes offline.

The KData approach

We design invoice automation around your existing systems, processing requirements and approval policies, connecting incoming invoice channels with document storage and downstream workflows. Repetitive handling goes down, and people stay involved where judgment is required.

The solution can include
  • Automated intake from designated mailboxes
  • Invoice document capture and organized storage
  • Scheduled processing that runs independently of user devices
  • Validation and exception routing for items requiring attention
  • Processing visibility and operational guidance for finance and IT

The scope can extend from automating a single repetitive step to connecting a broader invoice workflow.

Client quote to be added
“The client's own words on the outcome will appear here.”
Name, Title · Company type
Designed to support

Less manual administration, more consistent document handling, and clearer visibility into invoices requiring action.Results depend on the systems connected, invoice complexity and the level of automation implemented.

AI/BI dashboardsFleet analyticsDatabricks
Case study 02

Understand your fleet with AI-powered BI dashboards

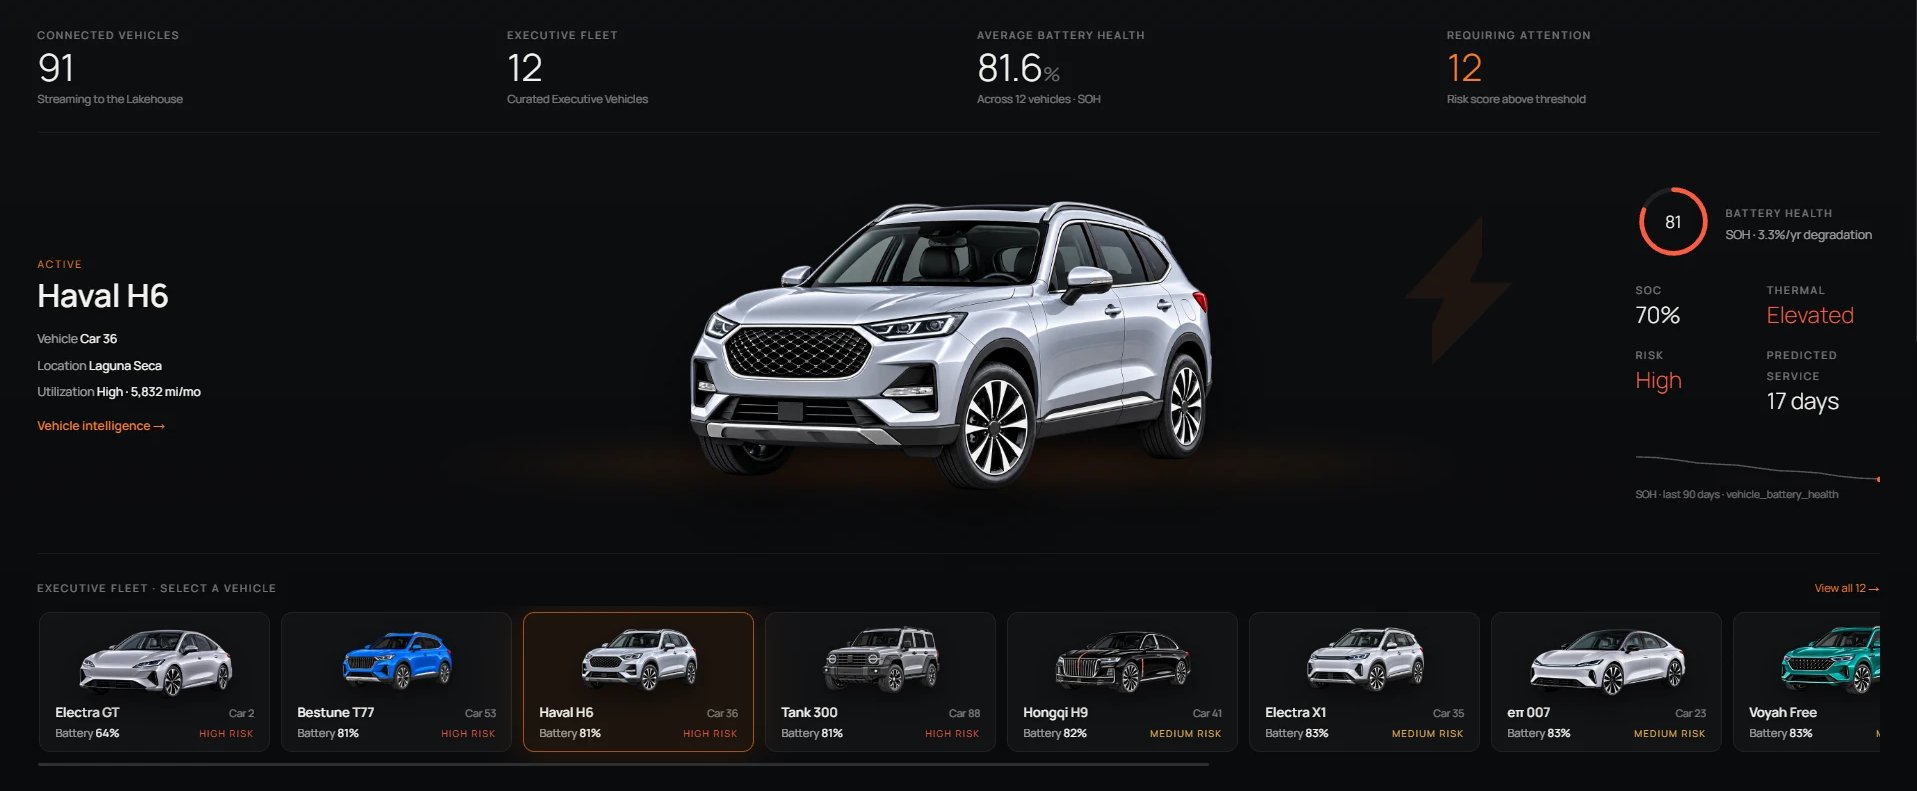
Turn vehicle data into clear, interactive insights. KData helps organizations bring fleet information together through dashboards and conversational analytics, making it easier to monitor performance, explore trends and answer operational questions.

Talk to us about AI/BI dashboards
Fleet intelligence dashboard: 91 connected vehicles, 12 executive fleet vehicles, 81.6% average battery health and 12 vehicles requiring attention, with a selected vehicle's battery health, state of charge, thermal status, risk and predicted service date, and a selectable fleet strip
Delivered dashboard · client details removed · click to enlarge
The business challenge

Fleet data often sits across disconnected sources and technical reports. Business users depend on analysts to prepare summaries, investigate changes and explain what the numbers mean. Static dashboards show what happened while leaving follow-up questions unanswered.

The KData approach

We design AI/BI dashboards around the decisions your teams need to make. Curated data, consistent business definitions and natural-language exploration help users move from a fleet-wide overview to the detail behind a trend, on a governed Databricks foundation that aligns access, metric definitions and reporting across teams.

Dashboards can include
  • Fleet performance overview: vehicle activity, utilization and operational indicators in one place
  • Battery and charging insights: charge levels, temperature patterns and charging behavior over time
  • Interactive exploration: filter, compare and drill into individual vehicles or groups
  • Conversational analytics: ask questions in plain language and review the supporting data
  • AI-assisted summaries: findings turned into concise explanations for operational reviews
Client quote to be added
“The client's own words on the outcome will appear here.”
Name, Title · Company type
Designed to support

Faster access to insights, less repetitive reporting work, and more independent exploration by business users.AI-generated answers stay traceable to the underlying data and available for review.

Legacy modernizationData migrationEmbedded quality
Case study 03

Move from Netezza to Databricks with confidence

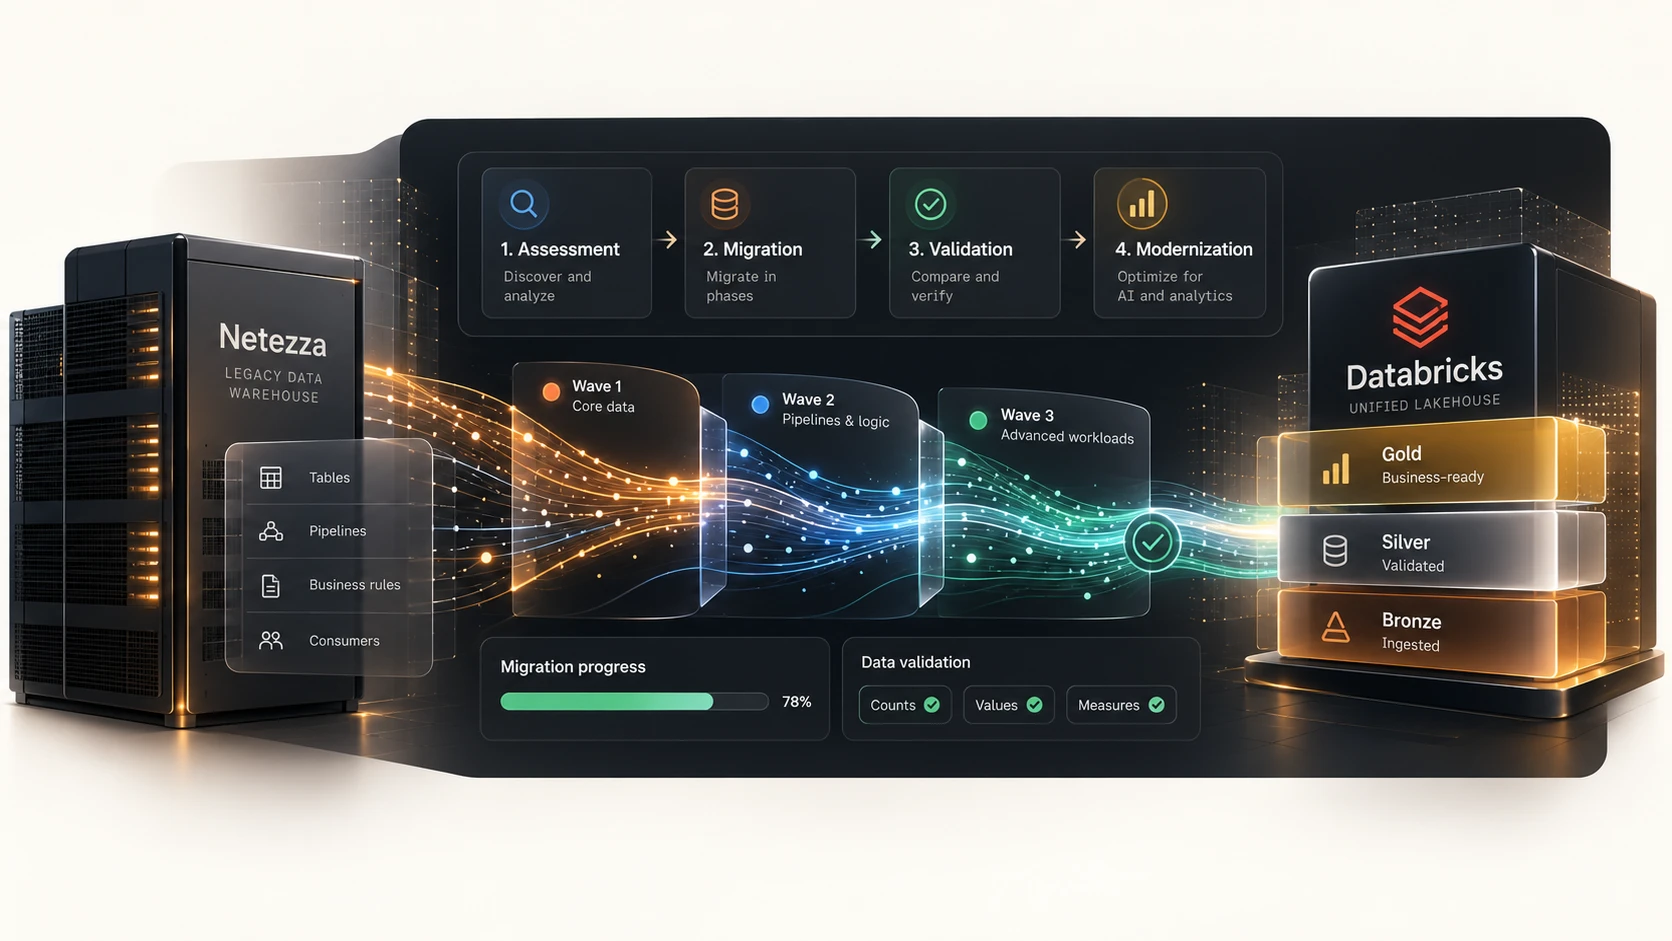
Modernizing a data platform takes more than converting code. KData helps organizations plan and deliver Netezza-to-Databricks migrations around trusted data, business continuity and manageable delivery stages.

Assess my Netezza environment
Netezza to Databricks migration overview: tables, pipelines, business rules and consumers move from the Netezza warehouse in three waves, through assessment, migration, validation and modernization, with counts, values and measures validated, into Databricks bronze, silver and gold layers
Migration overview · click to enlarge
The business challenge

Legacy platforms accumulate complex dependencies, undocumented business rules and processing patterns that need careful redesign. Moving workloads without understanding these details can introduce reporting differences, unexpected rework and uncertainty at cutover.

A successful migration needs to establish that the new platform supports the business processes and data its users rely on.

The KData approach

KData structures migration into prioritized waves, with clear quality checks and acceptance criteria throughout delivery.

Quality built into delivery

KData's AutoDQ and i-QA accelerators can support pipeline-level data quality checks and dataset test generation. Their use is scoped to the migration's requirements, helping teams make validation repeatable across workloads.

How each wave is delivered
  • Discover before converting: map tables, pipelines, business rules and downstream consumers; decide what to migrate, redesign or retire
  • Combine automation with engineering judgment: automate repeatable conversion work and route complex transformations for targeted review
  • Build a trusted data foundation: organize ingestion, validation and business-ready datasets in a layered lakehouse
  • Validate continuously: check record counts, field values and business measures throughout, not only before launch
  • Run platforms in parallel: compare outputs and resolve or formally accept differences before moving critical workloads
  • Control the transition: confirm downstream readiness, establish recovery plans and retire legacy dependencies in stages
Client quote to be added
“The client's own words on the outcome will appear here.”
Name, Title · Company type
Designed to support

A controlled transition, earlier visibility into migration risks, and stronger evidence for go-live decisions.The resulting Databricks foundation can support governed reporting, AI/BI dashboards and future analytics initiatives.

AI-powered data qualityAutomated validationDatabricks
Case study 04

Build trust into every pipeline with AutoDQ

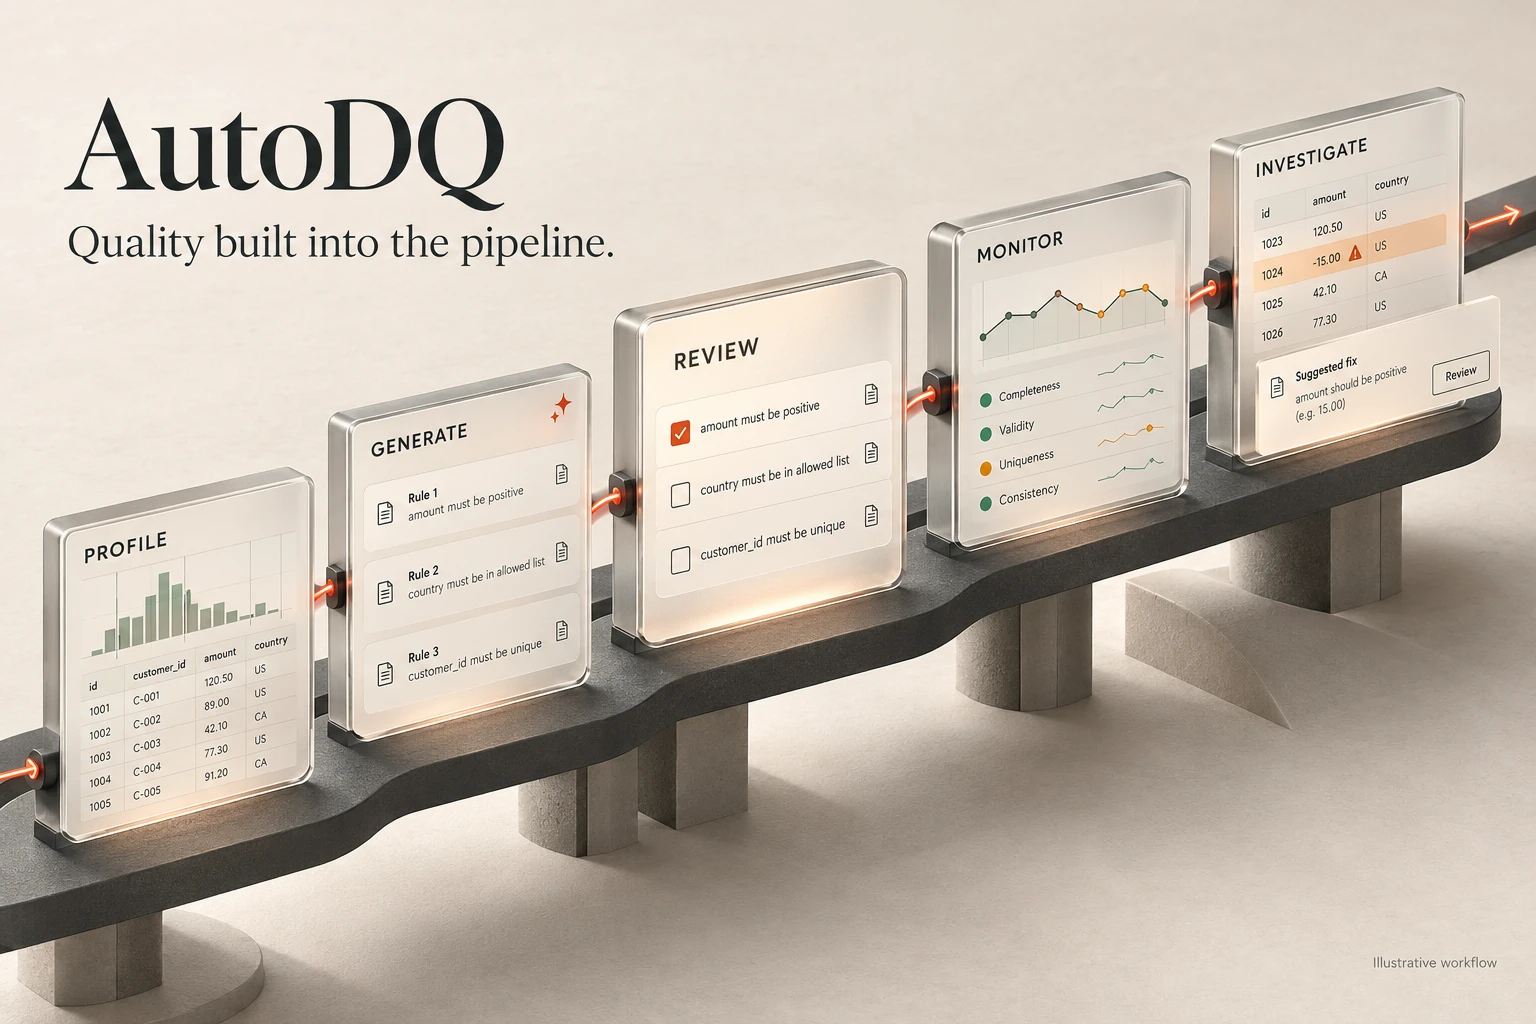
Reliable analytics starts with reliable data. AutoDQ, KData's data quality accelerator, brings profiling, validation and monitoring into the Databricks environment, helping teams identify issues before they affect dashboards, reporting and AI applications.

Explore AutoDQ
AutoDQ, quality built into the pipeline: an illustrative workflow of five panels along a pipeline, profile, generate rules, review, monitor and investigate with a suggested fix
Click to enlarge
The business challenge

As data pipelines grow, manual validation becomes difficult to maintain. Teams write checks individually, investigate recurring discrepancies and spend valuable time explaining why reports disagree.

Without consistent quality controls, problems can travel through multiple transformations before business users discover them.

The AutoDQ approach

AutoDQ embeds data quality checks into everyday pipeline operations. AI-assisted rule generation helps teams establish validation coverage, while monitoring and plain-language explanations make issues easier to understand and investigate.

Running natively within Databricks, AutoDQ brings these capabilities closer to the pipelines and datasets teams already manage.

The solution supports
  • Data profiling: patterns, distributions and quality trends that show where checks are needed
  • Automated validation: schema, format, business-rule and cross-table checks
  • Continuous monitoring: quality metrics and anomaly flags with configurable alert thresholds
  • AI-assisted investigation: issues explained, with corrective actions suggested in plain language
  • Controlled remediation: supported fixes through configurable approval workflows and audit logging
From detection to action
  1. ProfileProfile the dataset to see where checks are needed.
  2. GenerateGenerate candidate validation rules with AI assistance.
  3. ReviewReview the rules against business requirements.
  4. Embed & monitorAdd approved checks to pipelines and monitor the results.
  5. Investigate & fixInvestigate affected data and assess suggested fixes before acting.
Client quote to be added
“The client's own words on the outcome will appear here.”
Name, Title · Company type
Designed to support

Less repetitive rule-authoring work, earlier visibility into data problems, and more consistent validation across datasets.These controls help establish a stronger foundation for trusted AI/BI dashboards and downstream applications.

On-premises AITest generationQuality engineering
Case study 05

From business requirements to structured test suites with i-QA

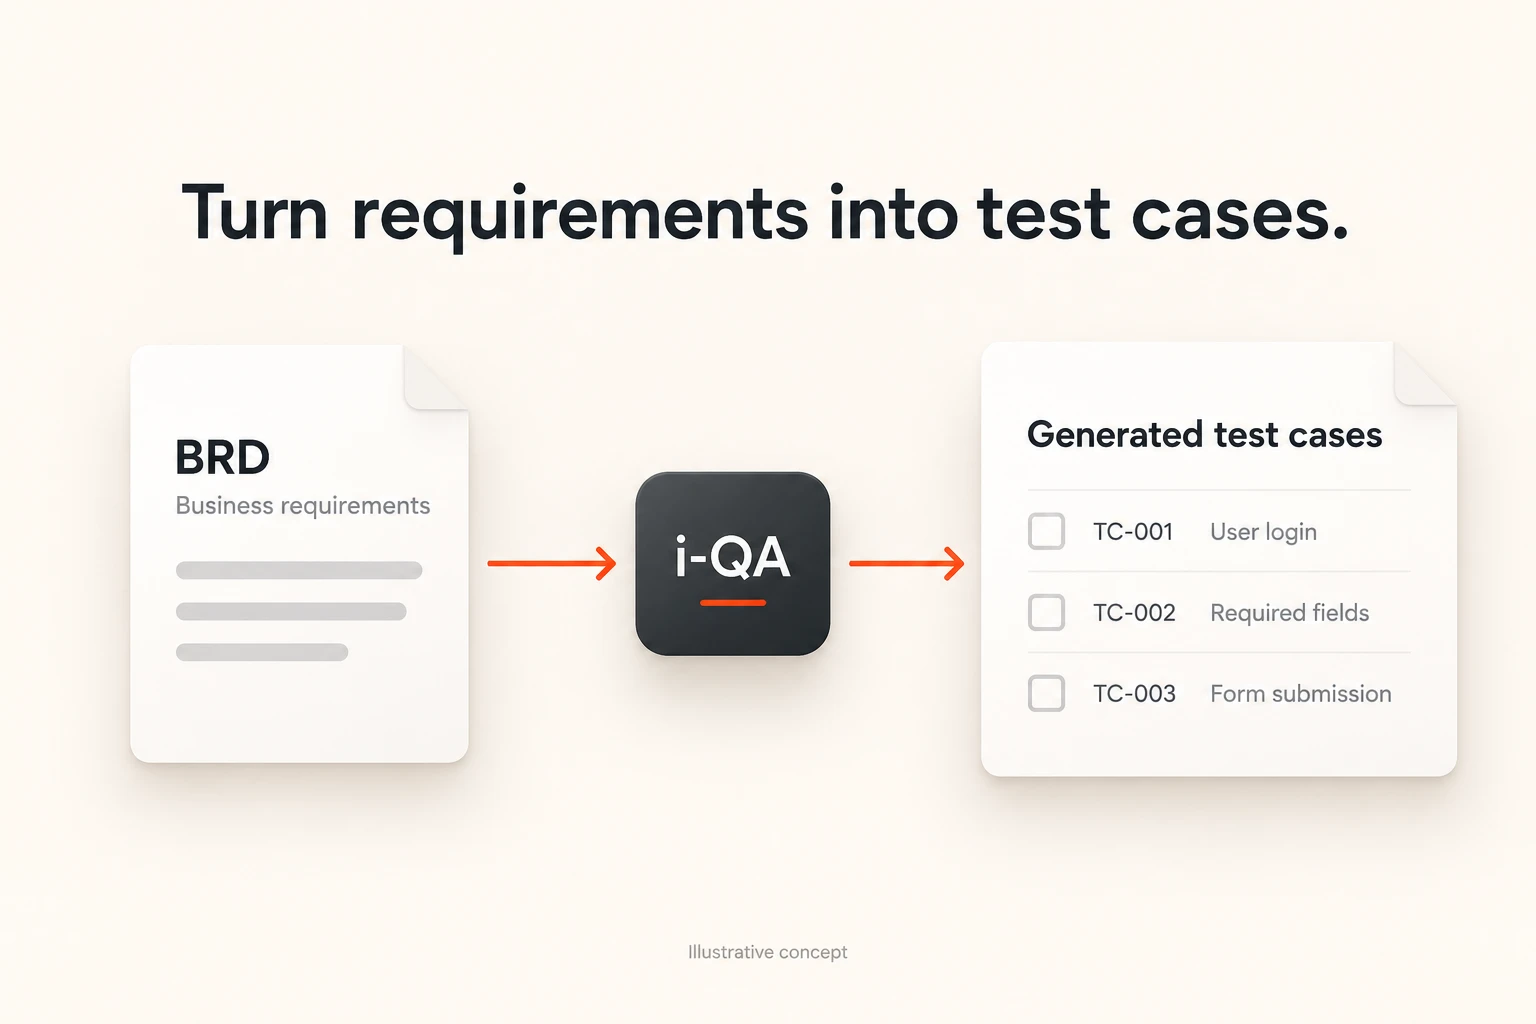
Turning business requirements into comprehensive tests takes time. i-QA, KData's AI-powered test-generation platform, helps teams translate Business Requirements Documents into structured test cases, automation files and supporting documentation within their own infrastructure.

Product solution story · not a completed client engagement
Talk to us about i-QA
Turn requirements into test cases: a business requirements document flows through i-QA and becomes a list of generated test cases such as user login, required fields and form submission
Click to enlarge
The business challenge

QA teams must interpret requirements, map them to application behavior, and create tests across interfaces, APIs, databases and business logic. Manual authoring can lead to inconsistent coverage and repeated work whenever requirements change.

For organizations handling sensitive information, AI also raises a deployment question: how can teams automate test generation while keeping requirements, schemas and business rules within their controlled environment?

The i-QA approach

i-QA uses locally deployed AI models to analyze requirements and generate test assets. Its core processing runs on the organization's infrastructure without requiring external AI services.

The workflow connects requirements analysis, test generation and documentation, giving QA teams a structured starting point for review and execution.

The solution supports
  • UI/UX testing: user journeys, interface behavior and input validation
  • API and middleware testing: authentication, error handling and integration checks
  • Database validation: schema consistency, data integrity and migration checks
  • Business logic testing: workflows, business rules and edge cases
  • Automation outputs: generated pytest files for review and integration into your test environment
  • Documentation: reports supporting UAT, sign-off and audit review
From requirements to execution
  1. UploadProvide the BRD for processing within the local environment.
  2. MapConnect requirements to relevant test targets and data models.
  3. GenerateProduce structured test cases, automation files and documentation.
  4. Review & executeConfirm coverage, configure environment details and run approved tests.
  5. UpdateUse delta mode to focus generation on changed requirements.

Human review remains part of establishing that generated tests accurately reflect business intent and are suitable for the target environment.

Control and traceability

Local processing helps organizations retain control over sensitive project information. Execution history and analyst attribution support traceability, while multi-user access lets teams manage concurrent generation work.

Deployment should reflect the organization's connectivity requirements. Optional Microsoft Teams notifications require connectivity to Teams and would be excluded from a fully air-gapped configuration. Audit records can support compliance processes; they do not independently establish regulatory compliance.

Designed to support

Less repetitive test-authoring work, more consistent coverage across application layers, and clearer connections between requirements and testing.Actual time savings and coverage improvements should be measured against the team's existing QA process.

More migration case studies

Every legacy platform, one destination.

Production migrations to Databricks from Teradata, DB2, SAS and SQL Server, plus Databricks on Google Cloud. Open a card for what we did and the outcome.

TeradataDatabricksEnterprise

Teradata to Databricks migration

A major North American organization ran a large-scale Teradata environment for critical reporting, operations and planning, until it became a bottleneck.

  • BTEQ batch jobs missing SLAs
  • High AMP-based licensing costs
  • Coupled FastLoad / MultiLoad pipelines
What we did & outcome What we did
  • Full discovery of databases, BTEQ scripts, stored procedures, macros and FastLoad / MultiLoad utilities
  • Converted Teradata DDLs, SQL, BTEQ and stored procedures to Databricks with automated tooling
  • Migrated schema and data into a bronze, silver and gold lakehouse
  • Governance, access control and auditability with Unity Catalog
  • Phased migration with validation, parallel runs and controlled cutover
Outcome
  • A production-ready Databricks platform, not just a migration
  • Modernized without disrupting mission-critical systems
DB2DatabricksTier-1 railroad

DB2 to Databricks migration

A major North American railroad ran a large DB2 environment for critical reporting, operations and planning workflows that had become a bottleneck.

  • Long-running batch jobs
  • High infrastructure and licensing costs
  • Tightly coupled ETL and database logic
What we did & outcome What we did
  • Full discovery of data assets, schemas, pipelines, SQL workloads and dependencies
  • Migrated schema and data into a bronze, silver and gold lakehouse
  • Refactored DB2 SQL, ingestion logic and transformation pipelines for Databricks
  • Governance, access control and auditability with Unity Catalog
  • Phased migration with validation, parallel runs and controlled cutover
Outcome
  • Improved pipeline performance and reliability
  • Reduced platform complexity and operational overhead
  • A unified foundation for analytics, reporting and AI, without disrupting core operations
SASDatabricksLarge enterprise

SAS to Databricks migration

A large enterprise ran an extensive SAS environment for critical ETL, reporting and analytics across multiple business domains.

  • SAS Grid jobs blocking downstream work
  • High SAS licensing costs
  • Procedural macro logic tied to legacy flows
What we did & outcome What we did
  • Inventoried and prioritized SAS datasets, macros, stored processes, ETL jobs and PROC SQL workloads
  • Migrated historical SAS data to Delta in bronze, silver and gold layers
  • Refactored DATA steps, PROC SQL and macros into PySpark notebooks and Python UDFs
  • Governance, access control and lineage with Unity Catalog
  • Phased migration with parallel runs, data reconciliation and controlled cutover
Outcome
  • Significantly faster pipelines than the legacy SAS Grid
  • Eliminated SAS licensing costs and reduced infrastructure complexity
  • A unified lakehouse for analytics, reporting and AI, without disrupting core operations
SQL ServerDatabricksEnterprise data warehouse

SQL Server to Databricks migration

A large enterprise ran a complex SQL Server data warehouse supporting critical reporting, analytics and operational workflows.

  • SQL Agent batch jobs slowing operations
  • Enterprise core licensing costs
  • Coupled SSIS and stored procedure logic
What we did & outcome What we did
  • Full discovery of schemas, pipelines, T-SQL workloads, SSIS packages and dependencies
  • Migrated schema and data into a bronze, silver and gold lakehouse
  • Refactored T-SQL, SSIS ingestion and transformations with Spark SQL and PySpark
  • Governance, access control and auditability with Unity Catalog
  • Phased migration with validation, parallel runs and controlled cutover
Outcome
  • Improved pipeline performance and reliability
  • Reduced platform complexity and operational overhead
  • A unified foundation for analytics, reporting and AI, without disrupting core operations
GCPDatabricksTier-1 railroad

Databricks on Google Cloud, built right first time

A major North American railroad implemented Databricks on GCP to modernize its data platform for analytics and AI, within GCP's specific constraints.

  • Service-account IAM across projects
  • Private Service Connect and VPC design
  • Coexistence with BigQuery and legacy systems
What we did & outcome What we did
  • Defined the target operating model across environments, domains and ownership
  • Designed identity and access with service accounts aligned to Unity Catalog
  • Architected VPC structure and private connectivity
  • Established GCS storage strategy with clear domain separation
  • Deployed and validated workspaces, access patterns and data flows before rollout
Outcome
  • A production-ready Databricks platform on GCP, built correctly from the start
  • Clear governance model across data, identity and access
  • No rework needed after deployment, thanks to early architecture decisions
Demo

See it running.

Short walkthroughs of KData's accelerators, running natively in Databricks or on your own infrastructure.

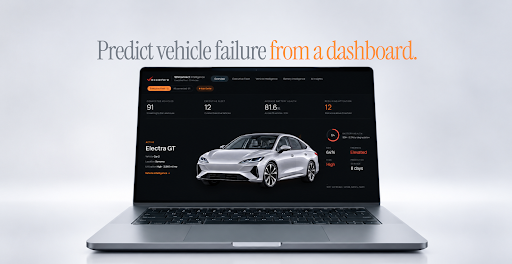
Excelfore vehicle intelligence dashboard on a laptop: Predict vehicle failure from a dashboardYouTubeWatch the Excelfore demo
Excelfore · Fleet analytics · Databricks

Excelfore: vehicle intelligence

Predict vehicle failure from your dashboard: battery health, risk scores and AI-recommended actions across a connected fleet, built on Databricks.

Request a demo
Careers

Shape the future of data.

Join a team transforming how organizations unlock the power of their data, working with leading AI and data technologies alongside industry experts.

50+team members
4.9/5employee rating
25vacation days
$2Klearning budget
Value

Innovation first

We embrace leading data and AI technologies and encourage creative solutions to complex challenges.

Value

Collaboration

Great ideas come from working together, in an environment where every team member thrives.

Value

Growth mindset

We invest in our people through continuous learning and career development.

Comprehensive health, dental & visionFlexible hours & remote optionsCompetitive salary & equityPerformance bonusesConference attendance & mentorshipHome office setupTeam retreats & events
Step 1Apply

Send your resume and a cover letter on why the role excites you.

Step 2Screen

A phone or video call with our talent team.

Step 3Interview

Meet team members and hiring managers to go deep on your experience.

News

From the field.

Events, guides and announcements from KData.

Event · Sep 2026

ALL IN 2026, Montréal

One of the applied AI events on KData's calendar, at the Palais des congrès de Montréal.

All events
Event · Jun 2026

GCP Databricks Executive Lunch

Hosted by KData and Databricks at Google Toronto, on the Data Intelligence Platform on Google Cloud.

All events
Guide

Migrating IBM Netezza to Databricks

A risk-managed approach: discovery, factory model, medallion architecture and a living risk register.

Read the guide
eBook

The Big Book of Data Science Use Cases

Use cases that actually deliver business value on Databricks, and how to get them into production.

Get the eBook
A delivery team collaborating around laptops (stock photo placeholder)
Our team

Embedded with your team. Not advisory-only.

Databricks + ClaudeDatabricks-certified expertise and a registered Claude partner.
Small, senior teams2–5 senior experts, embedded with yours.
Quality embeddedData quality built into pipelines, not layered on.
Aligned to ROIWork tied to real platform usage and business impact.
Leadership & delivery

The people on the rope.

KData's founder, practice leads and engineers behind its Databricks, Informatica and AI work.

Karthik MuthuramanKarthik MuthuramanFounder
Susruth ChunduruInformatica Practice Lead
John Xavier K.Databricks Practice Lead
Srikanth ASrikanth ASr. Databricks ML & AI Engineer
Shilpa SathishShilpa SathishData Engineer
Janavi RamakrishnanJanavi RamakrishnanAI Field Engineer
Partnership

Built with the right partners.

KData is a Databricks consulting partner and a registered Claude partner, and implements Informatica's cloud governance and quality platform.

Data governance & qualityInformatica

Implementation of Informatica Cloud Data Governance & Catalog (CDGC) and Cloud Data Quality (CDQ).

See CDGC & CDQ
Claude AI automationFinance operationsAccounts payable
Claude success story · Endurance Environmental

Transforming invoice management with Claude AI automation

From manual invoice processing to intelligent, AI-powered financial workflows.

Connected toOutlookOneDriveQuickBooks
Talk to us about Claude
What changed
  • Invoice intakeSupplier invoices collected, read and filed automatically
  • Duplicate checksRepeat invoices caught before they are processed
  • ApprovalsEvery invoice tracked by status, from review to accounting
  • Leakage alertsBilling gaps and low-margin work orders flagged for review
The challenge

Endurance Environmental needed a smarter, more efficient way to manage supplier invoices, streamline approvals and gain better visibility into financial performance.

Manual invoice processing, disconnected systems and limited visibility into billing discrepancies made it hard to keep accurate records, track profitability and identify potential revenue leakage.

Our solution: Claude AI-powered automation

KData developed an intelligent invoice management and financial reconciliation solution using Claude AI automation to streamline workflows, reduce repetitive manual tasks and improve financial visibility.

The application connects Outlook, OneDrive and QuickBooks, bringing invoice intake, document processing, approvals and financial analysis into one connected workflow.

Key Claude AI automation capabilities
  • Intelligent invoice processing: extraction of supplier details, invoice numbers, amounts and other financial information
  • Email and document management: invoice collection, naming, organization and movement through approval
  • AI-driven duplicate detection: repeated documents and supplier invoice numbers caught before duplicate processing
  • Automated approval workflow: invoices organized by status, from awaiting review to approved for accounting
  • Financial leakage and margin analysis: reconciliation of revenue and costs, flagging billing discrepancies and work orders below expected margin
  • Document traceability: organized records and supporting documents for review, reconciliation and audit
  • QuickBooks integration: direct accounting entry with approved invoice PDFs attached
The outcome

KData helped Endurance Environmental establish a more connected and intelligent invoice management workflow, bringing together automated document handling, structured approvals, financial reconciliation and exception detection. Repetitive administrative work went down, and invoice processing and profitability became easier to see.The result: a scalable, AI-powered foundation for smarter accounts payable management and financial decision-making.
Platform partnerDatabricks

Go-Live in 90 Days aligns with Databricks' Pilot to Production initiative, with co-selling and co-funding options available.

CloudGoogle Cloud

Databricks on GCP implementations, and executive events co-hosted with Databricks at Google Toronto.

Events & ecosystemPartner with us

We attend and host AI and data events across Canada and the US. Planning one? We'd like to hear about it.

Request KData at your event
Contact

Plan your route to production.

Planning a migration or stuck short of production? Let's assess your Netezza or legacy platform and define a production path.

Base campExchange Tower, 130 King Street West, Suite 1900Toronto, ON M5X 2A2contactus@kdataai.com · 1 833 532 8286

Opens your email app with your request addressed to contactus@kdataai.com.